Back to all news
Expert Consensus Sets Standardized Evaluation for Clinical Large Language Models
Tags:Policy
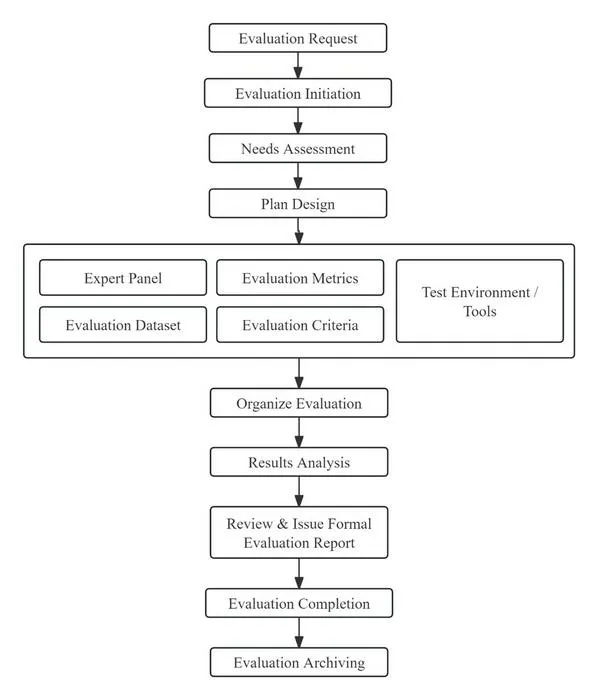
An expert consensus provides a robust, evidence-based framework for retrospective evaluation of large language models in healthcare.
Key Details
- 1Published in Intelligent Medicine, 1 November 2025 (DOI: 10.1016/j.imed.2025.09.001).
- 2Framework emphasizes scientific rigor, ethics, and transparency in LLM evaluation.
- 3Covers six LLM capability domains, including diagnosis support and multimodal dialogue.
- 4Recommendations agreed by 35 multidisciplinary experts using formal guideline methods.
- 5Evaluation metrics integrate both quantitative and qualitative measures for clinical applications.
- 6Stresses need for patient data protection and bias mitigation during assessment.
Why It Matters
A standardized, transparent evaluation is essential as large language models become integral to clinical workflows—including radiology—for diagnostic, documentation, and communication tasks. The framework ensures AI tools are effective, safe, and ethically deployed in real-world healthcare settings.
Source
EurekAlert
Related News
•EurekAlert
Pediatricians Receive AAP Guidance for Safe Use of Generative AI
The American Academy of Pediatrics has issued recommendations to ensure the safe, equitable, and effective use of generative artificial intelligence in pediatric clinical care.
•EurekAlert
Legal Gaps in Explaining AI Decisions to Patients in Imaging
A JMIR article examines the disconnect between AI legal requirements and actual patient comprehension in medical imaging and diagnostics.
•EurekAlert
Editorial Warns of AI's Risk to Critical Thinking in Medical Education
Generative AI may undermine critical thinking skills and reinforce bias in new doctors, warns BMJ editorial.